• Pl chevron_right

      Matthew Garrett: Epic's EAC2 v2 seems fairly easily bypassable

      news.movim.eu / PlanetGnome • 20:23 • 3 minutes

    Epic just announced the upcoming version 2 of their Linux implementation of Easy Anti-Cheat. It’s based on using the Linux eBPF security module to monitor what’s happening, and then a bunch of extra infrastructure to make sure this can’t be bypassed. The core part of this is requiring secure boot be enabled (ensuring that modified kernels can’t be used), using measured boot to verify that secure boot is enabled and which keys are used (to prevent you from just signing your own modified kernel), and then doing remote attestation, a mechanism where the TPM generates a signed copy of the boot measurements and passes that off to a server which verifies it came from a real TPM, verifies that you have secure boot enabled and are using the right keys, and presumably then allows you into the game.

    This is all fine as long as you can prove that the measurements provided are real, and that’s actually a lot harder than you might think. First, we can simply make up our own quote signed with our own key and say that it came from a TPM. This is avoided by every TPM having an Endorsement Key (or EK) and an associated certificate, with that certificate being signed by the TPM vendor. If you have a list of all the legitimate TPM vendors and their CA keys, you can verify that the measurements came from a real TPM. Easy enough. So we need to get the measurements from a real TPM, and the one on our motherboard contains the measurements that were generated by the firmware and bootloader, and we can’t reset those at runtime without resetting the TPM, which… oh huh there’s actually nothing stopping us from doing that at runtime, as long as we have access to the hardware. Many desktop boards have the TPM on a small plugin module with a standard pinout that includes a reset pin. Simply short that to ground briefly and the TPM is back in its initial state, and userland can write whatever measurements it wants to it. Boot a modified kernel which lies to the eBPF code? As long as you replay the expected log values from a boot with secure boot on and a trusted kernel, the TPM will still happily provide a legitimate set of measurements that’ll satisfy the checker.

    What if the TPM is less accessible, either because it’s mounted directly to the motherboard or it’s inside the CPU or chipset? That’s going to be trickier. But here’s the thing. The quote needs to come from a TPM, but not necessarily the TPM on your motherboard. TPMs these days are usually connected via the Serial Peripheral Interface, usually referred to as SPI. Microchip make a USB to SPI bridge, and there’s a Linux driver. Wire one of those up with an appropriate header and you can plug in an easily available TPM module intended for plugging into a motherboard, and now we tell the kernel to ignore the motherboard TPM and make /dev/tpmrm0 point at the USB one and program it with a set of trusted measurements and once again everything is going to look just fine (yes obviously the eBPF code can look for this, but we’re running a modified kernel so we can just lie to the eBPF code).

    Remote attestation on PCs just doesn’t work that well in environments where you can’t associate a specific TPM with a specific system, which is basically everywhere except enterprises. But maybe that doesn’t matter and cheaters wouldn’t be willing to spend the $20 or so it’d take to produce one of these things? That would seem somewhat surprising, but it’s not impossible. And obviously any server-side cheat detection that triggers could then block that specific TPM, meaning they’d need to go and get another TPM, and maybe that ends up being enough to discourage people from bothering. From a practical level, this may be sufficient. But at a technical level? It’s not great.

    • Pl chevron_right

      Jussi Pakkanen: Implementing a simple version of ThreadPoolExecutor in Pystd

      news.movim.eu / PlanetGnome • 15:57 • 1 minute

    One of my favourite things in the Python standard library is the ThreadPoolExecutor. It is a very simple way to run a bunch of tasks in parallel, such as converting or repacking a whole bunch of image files from one format to another. You write a pure function that takes two arguments, the input and output file names, and does the conversion. Then you submit a bunch of tasks (basically function and argument pairs) and the executor runs them with maximal parallelism.

    I decided to implement this in Pystd. To make things simpler it does not yet support futures for return values. Writing a thread pool executor needs some fundamental building blocks such as threads, mutexes and condition variables. Once those were implemented (and working), writing the actual "business logic" turned out to be fairly simple. In fact, it took less time than writing the PNG processing code with libpng.

    First you need to write this helper class to register you task for running. It also stores all arguments etc that the task needs to do its thing. Yes, this has a bit of that "icky 90s Java" feeling to it but OTOH it is fairly simple, has unambiguous ownership semantics and compiles massively faster than your typical template monstrosity.

    task_interface.png

    Using this is just a matter of globbing for png files in the input dir and submitting tasks for them.

    task_submit.png

    The UX is a bit verbose. It could probably be made nicer with a helper method or two. Still, not too shabby for something written by hand in a single afternoon.

    For those interested in details, the code for this program is in the pngtest branch.

    • Pl chevron_right

      Christian Schaller: Using Artificial Intelligence to reverse engineer hardware

      news.movim.eu / PlanetGnome • 13:28 • 8 minutes

    After my mother passed away I ended up with a big box full of old film negatives containing photos from childhood family trips and similar. So I decided to buy a negative photo scanner and found that the Plustek 8200i was supported under Linux so I bought that. Only to discover that the chipset in the scanner had changed to one that wasn’t supported under Linux anymore. So I had some success making Linux configuration tools for some of my hardware using Claude code, like my Dell Camera controller app so I thought, maybe Claude can help me get a working SANE driver. I basically got stuck and got nowhere for the longest time and even basically gave up on the project for a few Months.

    Then I saw a post on X from Tom Crider aka Glorious Eggroll talking about how he had managed to fix a mouse driver using AI tooling. He basically described how he set it up so that the AI agent had full control of a Windows instance to capture data needed to fix the driver. So I pasted his tweet into Claude and asked it to help me set up a windows virtual machine to do the same things Tom as doing for my scanner. I think the combination of having the ability to run scans under windows and capture the USB data while doing so worked wonders, probably combined with improvements to Claude code made a huge difference. Within a few hours I had my first ever working scan under Linux, sure with some quality issues, but 100% recognizable as the image in the negative. Some days later I had a near perfect driver, including support for Infrared scanning ready to go, only to discover that in the time between me giving up and then trying again someone had committed code to SANE to support the scanner already…..it happens sometimes. I also used Claude to write an application for doing negative scanning, which I named Negative Vibes, thought that was a cute name.

    Anyway, with the success of my scanner effort I thought, I wonder if I can use this to finally fix the last issues with MIPI camera support on my laptop. So I told claude to re-use the harness I had created and try to fix the MIPI camera on my laptop by updating the kernel driver and libcamera as needed. I started the job in the morning and by the end of the day I had a much improved situation with patches for both the kernel and libcamera ready.

    So I thought that this might be worthwhile sharing with the world, and while anyone could start from scratch I did ask Claude to make the harness generic and document it to make the pathway for anyone else who wants to try this on their hardware a little easier. Writing a driver for undocumented hardware has always been tedious. You capture bus traffic, stare at hex dumps, and form hypotheses about what each register or control transfer does. You then test them one at a time, usually for weeks. None of it is conceptually hard, but it takes a lot of patience and skills.

    That kind of work suits an AI model well. It can read thousands of lines of USB capture, notice that a sequence repeats with one byte changing, and propose what that byte means. It can write the test to confirm it, and it doesn’t get bored. The human still decides what to build and checks that it works on real hardware, but the slog shrinks a lot.

    hw-harness

    Be aware that I did not use hw-harness in this form for my projects as this was basically bespoke code at that time, so this project is an attempt to make the harness more generic and shareable from the scripts I was using while doing the work. What hw-harness is meant to help your Claude or Codex session with:

    1. Record a reference session. Run the vendor’s Windows driver in a KVM virtual machine, with the real device passed through to the guest.
    2. Capture from outside the VM. Record the traffic on the Linux host with usbmon. It sits below the passthrough layer, so the guest can’t see it.
    3. Repeat the same operation on Linux with your own driver, and capture that the same way.
    4. Diff the two traces. Both come from the same instrument, so they compare directly. The differences are your list of driver bugs.

    For devices with no bus to tap, such as an internal MIPI camera, the harness uses Windows-side inspection instead. That means INF files, registry data, ACPI tables and device properties.

    The approach should be fine in the sense it doesn’t rely on copying any code instead it observes what the hardware does and only extract configuration data from the Windows drivers, so every constant in the new driver traces back to something recorded.

    So for those interested I have 3 short descriptions of the projects I did and what was needed.

    Project 1: a SANE backend for the Plustek OpticFilm 8200i

    comparison of two scanner drivers on same negative-

    Comparing the driver output of two drivers available.


    The first project is a SANE backend for the newer Plustek OpticFilm 8200i. It uses the Genesys GL128 controller (USB 07b3:1825) and had no Linux support. The older model with the same name uses a GL845 and is already handled by SANE.

    The backend supports:

    • Color, gray, infrared and color+infrared modes
    • Resolutions from 300 to 7200 dpi, at 8 or 16 bits per channel
    • Dust and scratch removal from the infrared channel
    • An exposure multiplier for dense negatives

    It’s packaged as a Fedora RPM, built automatically on every push. I mostly tested it with my own Negative Vibes application as there are not that many options under Linux for negative scanning.

    Upstream SANE’s genesys backend also gained support for this scanner in September 2026, so I compared the two. Both resolve the same fine detail at 3600 dpi. Mine is faster at full resolution (34.6 s against 54.4 s) and supports infrared dust removal. Upstream offers more resolution steps. The webpage has an interactive side-by-side comparison you can check out. These are single-unit, single-frame results, so treat them as one data point. Check out the interactive page I made showing the current state of the two drivers, hopefully the discoveries I made can be used by the SANE project to fix some smaller items in the upstream driver. Anyway, I put this project up more as a proof of concept due to that since I expect everyone including myself will use the upstream driver once it reaches parity with this one.

    Project 2: Negative Vibes

    Full scan of negative completed including infrared cleaning of image.


    A driver alone isn’t much use if scanning negatives is still painful, so I built Negative Vibes. It’s a GNOME app, written in Rust, for scanning colour and black-and-white negatives and slides on any film-capable SANE scanner.

    The scan is kept exactly as the scanner delivered it: 16-bit, linear, with the infrared plane. Everything else is a stack of non-destructive settings on top, so you can change the look and export again. It includes:

    • Density-space negative inversion with film base and dye-crosstalk correction
    • Roll-wide settings with per-frame overrides
    • Infrared and software dust removal
    • IT8 calibration through ArgyllCMS
    • Export to TIFF, JPEG, PNG and DNG, with ICC profiles and metadata

    It ships as a Flatpak that includes the scanner backend. It’s tested on the 8200i so far. The goal is to support any film scanner SANE supports. For that, SANE needs a standard way to expose infrared channels, which it doesn’t have yet.

    Project 3: Fixing the MIPI camera on my ThinkPad

    Showing MIPI output before and after fixes. Colors are better than they look as I was sitting in a relatively dark room by the end of the session.

    Showing MIPI output before and after fixes. Colors are better than they look as I was sitting in a relatively dark room by the end of the session.


    The camera in my Lenovo ThinkPad X1 Carbon Gen 14 (Aura Edition) uses a Sony IMX471 sensor behind an Intel IPU7. On Linux it produced dark images with heavy vignetting and a strong yellow-green cast. mipi-fixes-x1-aura collects the fixes. It’s only relevant to this laptop, which is why it isn’t one of the bigger packaged projects, but I have already submitted the kernel patches to Kate Hsuan and the libcamera patches is being reviewed by Wim Taymans for submission to Libcamera.

    Kernel (IMX471 driver):

    • A crop-selection bug returned an error before storing the crop rectangle, so libcamera assumed the full pixel array.
    • The test-pattern register was declared with the wrong width.
    • The analogue gain cap was too low, which cost about 1.8 stops of sensitivity.

    libcamera software ISP:

    • Lens shading correction was missing entirely, leaving the corners about 2.7 stops darker.
    • White-balance statistics were summed at the sensor’s native bit depth against an 8-bit black level. That skewed white balance, and the fix applies to any RAW10/RAW12 sensor.

    In a controlled low-light test, frame brightness rose from 31.1 to 90.9. The red/green and blue/green ratios moved from 0.890 and 0.672 to 1.047 and 0.823, close to a USB webcam reference. Blue is still about 17% short in low light, which I put down to grey-world white balance. Fedora 44 RPMs are on the releases page.

    What I learned

    • Reference captures are a big step. Having the AI compare a known-good trace against a failing one turns a vague “it doesn’t work” into a concrete list of differences. For example for the MIPI camera having a USB camera also connected so Claude could compare the two captures was critical.
    • The AI is good at the tedium. That covers decoding captures, writing probes and cross-checking constants. I still have to be the one holding the physical hardware.
    • Real hardware is the only judge. Every claim above was checked on the actual scanner or laptop.

    If you have hardware with no Linux driver, try hw-harness. Thanks again to Glorious Eggroll for the inspiration.

    NOTE: I am not claiming that my scans or MIPI camera is perfect now, but the scanner gives me decent looking scans and the MIPI camera looks a lot better than before. So over time I am sure we be able to tweak and polish further, but I am happy that it allowed me to move the needle despite lacking the in-depth knowledge for this type of work.

    —

    • Pl chevron_right

      Gedit Technology: gedit 51.0 released

      news.movim.eu / PlanetGnome • 10:00

    The gedit text editor version 51 has been released!

    A previous blog post, News, April-May 2026 already covers most of the changes.

    A reminder that gedit is still alive and is available to install, as an alternative.

    Progress has been made since May, but it's mostly under-the-hood changes, preparatory work to replace some internals and eventually make bigger visible changes to the application(s).

    B2B Services

    gedit is not only an application, there is a set of libgedit-* shared libraries underneath. This collection of re-usable code can be leveraged to create new products, and B2B services are possible.

    This was another reminder, but it cannot hurt ;-)

    • Pl chevron_right

      Jakub Steiner: Digger

      news.movim.eu / PlanetGnome • 0:00

    Digger

    The fact this movie tanked at the box office just makes the ride all the more enjoyable. I had a bad headache and had to call off the screening with a friend yesterday. Thursday is when the movies rotate in our part of the world where we use the un-American units, so I thought I'd missed yet another great cinematic experience. Luckily they still showed it in a small neighboring town, to the two of us and two other people, with an introduction by a charming young person.

    I don't remember anything these days, but I clearly remember when I saw Dr. Strangelove in Amherst, NH, in 1993. I was completely taken by the humor, despite thinking I'd never enjoy an ancient movie like that. It's probably way longer between my viewing and today than it was between then and the actual production of it. I don't wanna check.

    Anyhow, this is masterfully done cinema, and all four of us laughed out loud at the horrors we saw. Absolute must-see.

    ★★★★★

    • Pl chevron_right

      Jakub Steiner: Pixels Wallpaper Update

      news.movim.eu / PlanetGnome • 0:00 • 1 minute

    Usually I blog about new additions to the GNOME wallpapers after a release, to give some behind the scenes look on how they were produced. This time I'm asking for some feedback beforehand.

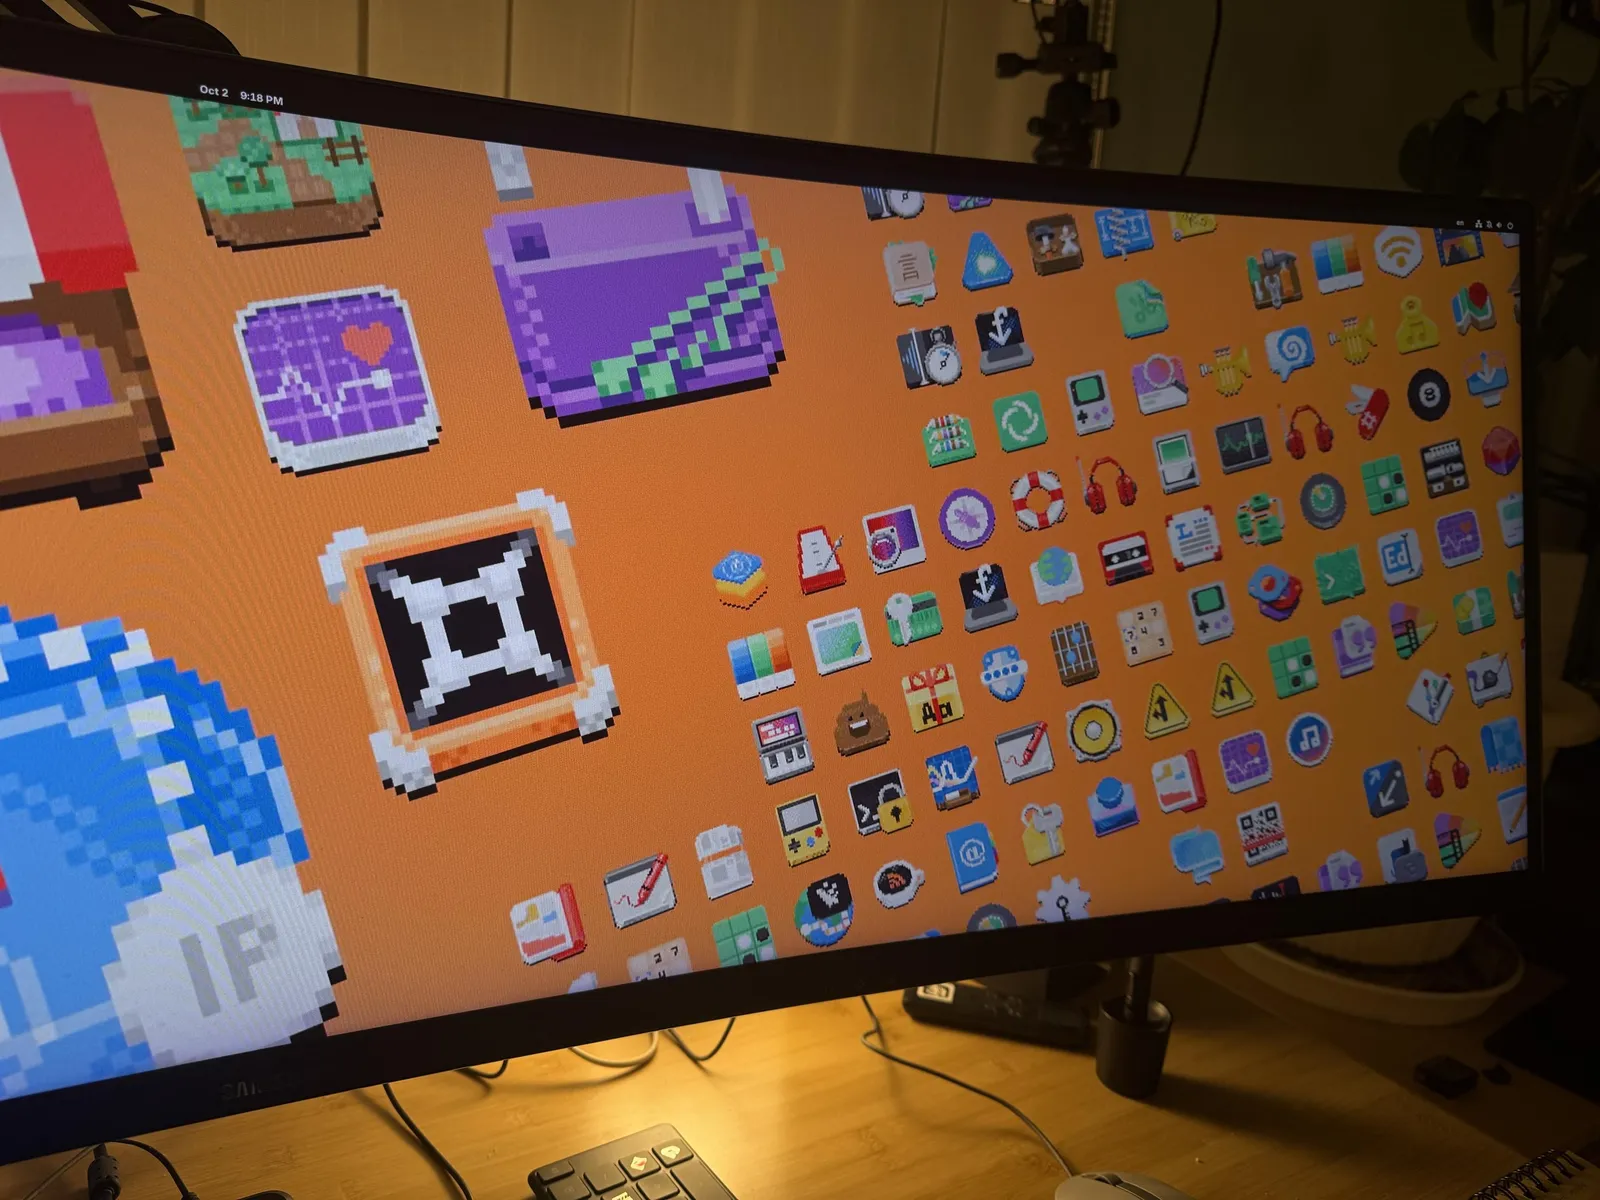
    Orange pixel art wallpaper variant with large foreground icons, photographed on a monitor

    Pixels has shipped as a wallpaper before. The wallpaper landed back in 2021 and keeps getting refreshed as new Circle apps join the lineup, and 47 added LCD and LCD-rainbow, revealing the curator's pixelart kink.

    The raw material is a side project years in the making — app icons redrawn as chunky pixels (Pixels, Mo' Pixels, Revert That Vector Nonsense!).

    The idea and layout remains the same as the old wallpaper. This time that's more than two variants though. The old Adwaita default used to cycle morning, day and night variants through a slideshow. While we switched to the dark/light variants, the format is still understood today. Thus pixelart comes in not 2, not 3, but 9 color variants. And here's where I'd like your feedback. Do you like the focus on contrast and having the whole set with dark background colors? Should there be more bright colors in the mix? Do you think the grain goes against the spirit of the pixel art? Is the small grid too toned down with the depth fog?

    As always, the Blender project files are available in wallpaper-assets if you want to poke at the node setup yourself:

    As with any wallpaper, don't judge it based on a preview, regardless of how large you view it. Apply it, use it. The most straightforward way to test GNOME development is with GNOME OS. It ships pixels and all the other wallpapers.

    • Pl chevron_right

      Lennart Poettering: Mastodon Stories for systemd v262

      news.movim.eu / PlanetGnome • 1 day ago • 1 minute

    On September 22 we released systemd v262 into the wild.

    In the weeks leading up to that release (and since then) I have posted a series of serieses of posts to Mastodon about key new features in this release, under the #systemd262 hash tag. In case you aren't using Mastodon, but would like to read up, here's a list of all 35 posts:

    I intend to do a similar series of serieses of posts for the next systemd release (v263), hence if you haven't left tech Twitter for Mastodon yet, now is the opportunity. My series for v263 will begin in a few weeks most likely, under the #systemd263 hash tag.

    In case you are interested, here is the corresponding blog story for systemd v261, here for v260, here for v259, here for v258, here for v257, and here for v256.

    • Pl chevron_right

      Juan Pablo Ugarte: Cambalache 1.2 Released

      news.movim.eu / PlanetGnome • 1 day ago

    Hello, I am pleased to announce a new Cambalache release.

    Cambalache is a WYSIWYG (What You See Is What You Get) tool that allows you to create and edit user interfaces for Gtk 4 and 3 applications.

    This new version depends on GNOME SDK 51 and includes all new properties and types from Gtk and Adwaita! It also removes the file hash from the project file which should prevent unnecessary git conflicts.

    In case you missed it, you can read more about Cambalache in version 1.0 release blog.

    Cambalache’s First Major Milestone!

    Help us continue developing

    If you find this application useful you can support it’s development by contributing on Liberapay or Patreon

    Where to get it?

    From Flathub

    flatpak remote-add --if-not-exists flathub https://dl.flathub.org/repo/flathub.flatpakrepo
    
    flatpak install flathub ar.xjuan.Cambalache

    or directly from gitlab

    git clone https://gitlab.gnome.org/jpu/cambalache.git

    Matrix channel

    Have any question? come chat with us at #cambalache:gnome.org

    Mastodon

    Follow me in Mastodon @xjuan to get news related to Cambalache development.

    As usual happy coding!

    • Pl chevron_right

      Matthew Garrett: Linux Lockdown and Hibernation (again)

      news.movim.eu / PlanetGnome • 2 days ago • 16 minutes

    (This is an updated version of an older post - the introduction remains the same, the technical details are different)

    Linux draws a distinction between code running in kernel (kernel space) and applications running in userland (user space). This is enforced at the hardware level - in x86-speak1, kernel space code runs in ring 0 and user space code runs in ring 32. If you’re running in ring 3 and you attempt to touch memory that’s only accessible in ring 0, the hardware will raise a fault. No matter how privileged your ring 3 code, you don’t get to touch ring 0.

    Kind of. In theory. Traditionally this wasn’t well enforced. At the most basic level, since root can load kernel modules, you could just build a kernel module that performed any kernel modifications you wanted and then have root load it. Technically user space code wasn’t modifying kernel space code, but the difference was pretty semantic rather than useful. But it got worse - root could also map memory ranges belonging to PCI devices3, and if the device could perform DMA you could just ask the device to overwrite bits of the kernel4. Or root could modify special CPU registers (“Model Specific Registers”, or MSRs) that alter CPU behaviour via the /dev/msr interface, and compromise the kernel boundary that way.

    It turns out that there were a number of ways root was effectively equivalent to ring 0, and the boundary was more about reliability (ie, a process running as root that ends up misbehaving should still only be able to crash itself rather than taking down the kernel with it) than security. After all, if you were root you could just replace the on-disk kernel with a backdoored one and reboot. Going deeper, you could replace the bootloader with one that automatically injected backdoors into a legitimate kernel image. We didn’t have any way to prevent this sort of thing, so attempting to harden the root/kernel boundary wasn’t especially interesting.

    In 2012 Microsoft started requiring vendors ship systems with UEFI Secure Boot, a firmware feature that allowed5 systems to refuse to boot anything without an appropriate signature. This not only enabled the creation of a system that drew a strong boundary between root and kernel, it arguably required one - what’s the point of restricting what the firmware will stick in ring 0 if root can just throw more code in there afterwards? What ended up as the Lockdown Linux Security Module provides the tooling for this, blocking userspace interfaces that can be used to modify the kernel and enforcing that any modules have a trusted signature.

    But that comes at something of a cost. Most of the features that Lockdown blocks are fairly niche, so the direct impact of having it enabled is small. Except that it also blocks hibernation6, and it turns out some people were using that. The obvious question is “what does hibernation have to do with keeping root out of kernel space”, and the answer is a little convoluted and is tied into how Linux implements hibernation. Basically, Linux saves system state into the swap partition and modifies the header to indicate that there’s a hibernation image there instead of swap. On the next boot, the kernel sees the header indicating that it’s a hibernation image, copies the contents of the swap partition back into RAM, and then jumps back into the old kernel code. What ensures that the hibernation image was actually written out by the kernel? Absolutely nothing, which means a motivated attacker with root access could turn off swap, write a hibernation image to the swap partition themselves, and then reboot. The kernel would happily resume into the attacker’s image, giving the attacker control over what gets copied back into kernel space.

    This is annoying, because normally when we think about attacks on swap we mitigate it by requiring an encrypted swap partition. But in this case, our attacker is root, and so already has access to the plaintext version of the swap partition. Disk encryption doesn’t save us here. We need some way to verify that the hibernation image was written out by the kernel, not by root. And thankfully we have some tools for that.

    Trusted Platform Modules (TPMs) are cryptographic coprocessors7 capable of doing things like generating encryption keys and then encrypting things with them. You can ask a TPM to encrypt something with a key that’s tied to that specific TPM - the OS has no access to the decryption key, and nor does any other TPM. So we can have the kernel generate an encryption key, encrypt part of the hibernation image with it, and then have the TPM encrypt it. We store the encrypted copy of the key in the hibernation image as well. On resume, the kernel reads the encrypted copy of the key, passes it to the TPM, gets the decrypted copy back and is able to verify the hibernation image.

    That’s great! Except root can do exactly the same thing. This tells us the hibernation image was generated on this machine, but doesn’t tell us that it was done by the kernel. We need some way to be able to differentiate between keys that were generated in kernel and ones that were generated in userland. TPMs have the concept of “localities” (effectively privilege levels) that would be perfect for this. Userland is only able to access locality 0, so the kernel could simply use locality 1 to encrypt the key. Unfortunately, localities are typically only available on systems that implement a Dynamic Root of Trust Measurement like Intel’s TXT, and most consumer systems have no support for this. So, we need another approach.

    TPMs have a set of Platform Configuration Registers (PCRs), intended for keeping a record of system state. The OS isn’t able to modify the PCRs directly. Instead, the OS provides a cryptographic hash of some material to the TPM. The TPM takes the existing PCR value, appends the new hash to that, and then stores the hash of the combination in the PCR - a process called “extension”. This means that the new value of the TPM depends not only on the value of the new data, it depends on the previous value of the PCR - and, in turn, that previous value depended on its previous value, and so on. The only way to get to a specific PCR value is to either (a) break the hash algorithm, or (b) perform exactly the same sequence of writes. On system reset the PCRs go back to a known value, and the entire process starts again.

    Some PCRs are different. PCR 23, for example, can be reset back to its original value without resetting the system. We can make use of that. The first thing we need to do is to prevent userland from being able to reset or extend PCR 23 itself. All TPM accesses go through the kernel, so this is a simple matter of parsing the write before it’s sent to the TPM and returning an error if it’s a sensitive command that would touch PCR 23. We now know that any change in PCR 23’s state will be restricted to the kernel.

    When we encrypt material with the TPM, we can ask it to record the PCR state. This is given back to us as metadata accompanying the encrypted secret. Along with the metadata is an additional signature created by the TPM, which can be used to prove that the metadata is both legitimate and associated with this specific encrypted data. In our case, that means we know what the value of PCR 23 was when we encrypted the key. That means that if we simply extend PCR 23 with a known value in-kernel before encrypting our key, we can look at the value of PCR 23 in the metadata. If it matches, the key was encrypted by the kernel - userland can create its own key, but it has no way to extend PCR 23 to the appropriate value first. We now know that the key was generated by the kernel.

    Unfortunately it turns out that some people actually make use of PCR 23, and restricting it to the kernel makes them sad. There are other resettable PCRs, but only in non-0 localities, so (a) we can’t reset them on most systems and (b) we’ll just find someone who uses them anyway and run into the same problem. We need a different approach.

    Thankfully TPMs have a small chunk of non-volatile RAM that can be used for storing things, and by “storing” I mean they can be used in a range of different ways. One of these is effectively as additional PCRs. These values can be configured such that they work the same way as PCRs, with the only way to modify them being to append a new hash to their existing value and update the new value to the hash of that merged value. We can allocate one of these for in-kernel use and reject any access from userspace, and also there are officially allocated ranges (so people shouldn’t be using random values) and the namespace is large enough anyway that w eshouldn’t collide with anyone, so we can carve one of those out and use it for this purpose.

    Unfortunately, though, these NV indexes aren’t included in the creation data we get when we create a key, so we need another approach. TPMs have the concept of sessions, a series of commands executed in sequence. A flag allows these sessions to be “audited”, with the TPM keeping a running track of the hash of the commands executed and the results returned. At the end of the session you can ask for a signed copy of this hash, and if you’ve kept a log of all the commands then you can verify that they match that signed hash and know that this log represents a real communication with the TPM. If we read the NV index and generate the key inside the same session, we can verify that the key we’re looking at was created while the NV index had a specific value, and if only the kernel can set that value then we know that the key was generated by the kernel.

    Or, well, can we? Only new kernels would impose the restriction on modifying that NV index. An attacker could boot an old kernel, generate a key there in userland, sign a hibernation image with it, and then reboot into a new kernel. The new kernel would see a valid signature with a valid NV index associated with it and have no way to know it was generated from userland rather than the kernel. We need to be able to tell the difference between kernels that implement this feature and ones that don’t, and we need to do that without being able to go back in time to change old kernel behaviour. We can extend a PCR to indicate we implement the new functionality, but so can an attacker running an old kernel.

    The normal approach to determining whether an event occurred in a specific phase of the boot process is to “cap” the PCRs - extend them with a known value that indicates a transition between stages of the boot process. Any events that occur before the cap event must have occurred in the previous stage of boot, and since the final PCR value depends on the order of measurements and not just the contents of those measurements, if a PCR is capped before userland runs, userland can’t fake the same PCR value afterwards. If Linux capped the PCRs before userland started running, we’d be able to place a measurement there before the cap occurred and then prove that that extension occurred before userland had the opportunity to interfere. We could simply place a statement that the kernel supported the NV index restrictions there, and we’d be fine.

    Unfortunately Linux doesn’t currently do this, and adding support for doing so doesn’t fix the problem - if an attacker boots a kernel that doesn’t cap a PCR, they can just cap it themselves from userland. So, we’re faced with the same problem: booting an older kernel allows the system to be placed in an identical state to the current kernel, and a fake hibernation image can be written out. Solving this requires a PCR that was being modified after kernel code was running, but before userland was started, even with existing kernels.

    Thankfully, there is one! PCR 5 is defined as containing measurements related to boot management configuration and data. One of the measurements it contains is the result of the UEFI ExitBootServices() call. ExitBootServices() is called at the transition from the UEFI boot environment to the running OS, and the kernel contains code that executes before it. So, if we measure an assertion regarding whether or not we support restricted access to NV indexes into PCR 5 before we call ExitBootServices(), this will prevent userspace from spoofing us (because userspace will only be able to extend PCR 5 after the firmware extended PCR 5 in response to ExitBootServices() being called). Obviously this depends on the firmware actually performing the PCR 5 extension when ExitBootServices() is called, but if firmware’s out of spec then I don’t think there’s any real expectation of it being secure enough for any of this to buy you anything anyway.

    That’s what this patchset does. Review feedback so far seems positive, although James Bottomley suggested a design improvement. My approach of using an NV index as a PCR and generating a signing key made sense as a consequence of my original approach involving PCR 23, which had been to use the key creation data and not use audit sessions at all. But the goal isn’t to use a key - it’s to prove that hibernation occurred in-kernel, and while signing is one way of doing that, there are others. His suggestion is to simply record the hash of the hibernation image into the NV index and then read that back as part of the audit session. On resume we verify the audit session log is legitimate, read the hibernation image, and compare the hash of the hibernation image against the hash in the log. If it matches, and if the PCR 5 value matches, we know the audit session happened in kernel and that the hibernation image hasn’t been modified.

    It still seems like we’re missing something, though. If we’re not storing a key anywhere, how do we verify the audit session? To explain this we’re going to need to go into some details about how TPM keys work in the first place. TPMs can produce a special kind of key called an Attestation Key, or AK. Attestation keys are used to sign attestation statements from the TPM, such as PCR quotes or audit logs. We need a separate key type for this in order to prove that the signature was generated as part of an attestation - normal TPM signing keys are fundamentally designed to sign arbitrary material, and so can be used by userland to sign something that looks identical to an attestation record. By being able to distinguish the types of key the TPM uses, we can prove that a signature was generated using an AK, and so know that it’s a real TPM attestation (because nothing other than the TPM can sign stuff with an AK).

    But even beyond this distinction, TPMs have different key types. Ordinary keys are generated using an RNG and will be unique. Primary keys are generated using a seed that is used as an input into a key derivation function. For a given TPM, using the same seed to generate the same type of primary key will always generate the same primary key8. We can have the kernel deterministically generate an AK during suspend in order to sign the audit log, and then generate the same key again on resume to validate it. This means we don’t need any other form of trusted storage for the AK - the TPM already provides that functionality.

    This is all rather complicated but I’ve been thinking about this for some time now and I haven’t come up with a cleaner solution. The only real open issue is the degree to which machines actually perform the PCR 5 extension. If it turns out there’s a bunch that don’t we’ll need to come up with some alternative approach to identifying whether the kernel supports this functionality, but the design is such that that should be invisible to userspace so adding alternatives later shouldn’t be an issue. Filtering accesses to the NV index is also not super clean, and depends on there not being alternative mechanisms to get at the TPM by sending raw commands. Again, this is intended to be opaque to userland and can be improved if we come up with something better later on (such as a secure way to pass a secret to the kernel on boot that can be used as an auth value for acess to the NV index).

    Anyway. Time to go and fix the next thing.


    1. Other architectures use different terminology here, such as “supervisor” and “user” mode, but it’s broadly equivalent ↩︎

    2. In theory rings 1 and 2 would allow you to run drivers with privileges somewhere between full kernel access and userland applications, but in reality we just don’t talk about them in polite company ↩︎

    3. This is how graphics worked in Linux before kernel modesetting turned up. XFree86 would just map your GPU’s registers into userland and poke them directly. This was not a huge win for stability ↩︎

    4. IOMMUs can help you here, by restricting the memory PCI devices can DMA to or from. The kernel then gets to allocate ranges for device buffers and configure the IOMMU such that the device can’t DMA to anything else. Except that region of memory may still contain sensitive material such as function pointers, and attacks like this can still cause you problems as a result. ↩︎

    5. This describes why I’m using “allowed” rather than “required” here ↩︎

    6. Saving the system state to disk and powering down the platform entirely - significantly slower than suspending the system while keeping state in RAM, but also resilient against the system losing power. ↩︎

    7. With some handwaving around “coprocessor”. TPMs can’t be part of the OS or the system firmware, but they don’t technically need to be an independent component. Intel have a TPM implementation that runs on the Management Engine, a separate processor built into the motherboard chipset. AMD have one that runs on the Platform Security Processor, a small ARM core built into their CPU. Various ARM implementations run a TPM in Trustzone, a special CPU mode that (in theory) is able to access resources that are entirely blocked off from anything running in the OS, kernel or otherwise. ↩︎

    8. Unless the TPM is cleared, in which case it’ll generate a new internal seed and now the keys will be different to before the clear ↩︎